|
Yang Zhou Hi, I'm a PhD student at the University of Toronto, supervised by Prof. Steven Waslander in the Toronto Robotics and AI Lab (TRAILab). Previously, I received my B.Eng. in Computer Science from Hunan University. My research interests span multimodal learning, world models, and intelligent agents. I am especially interested in integrating vision-language models with generative models to connect multimodal understanding and generation with action prediction and planning. Email / Google Scholar / Twitter / GitHub |
|
Research |
|
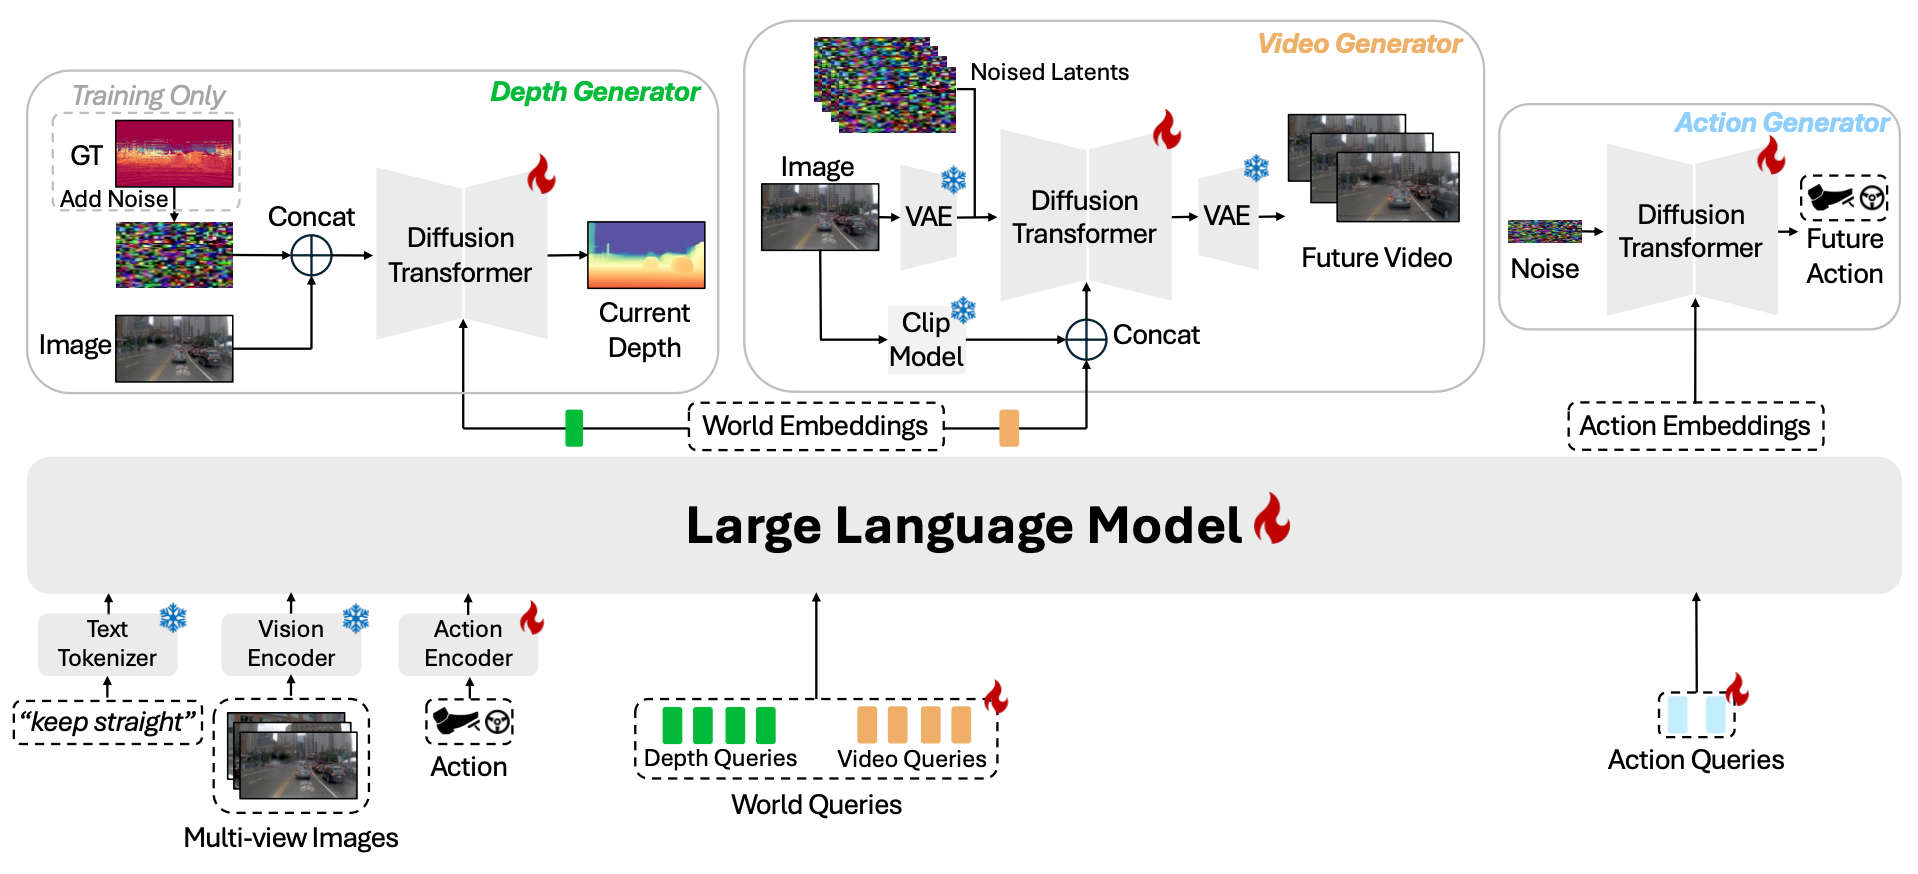
DriveDreamer-Policy: A Geometry-Grounded World-Action Model for Unified Generation and Planning
Yang Zhou, Xiaofeng Wang, Hao Shao, Letian Wang, Guosheng Zhao, Jiangnan Shao, Jiagang Zhu, Tingdong Yu, Zheng Zhu, Guan Huang, Steven L. Waslander NeurIPS, 2026 [Project Page] [Paper] [Code] A unified world-action model that jointly generates depth maps, future videos, and actions. |

|
LMGenDrive: LLM Reasoning Meets World Models for End-to-End Driving
Hao Shao, Letian Wang, Yang Zhou, Yuxuan Hu, Zhuofan Zong, Steven L. Waslander, Wei Zhan, Hongsheng Li ECCV, 2026 [Paper] LLM-based multimodal understanding with generative world models for end-to-end closed-loop autonomous driving. |
|
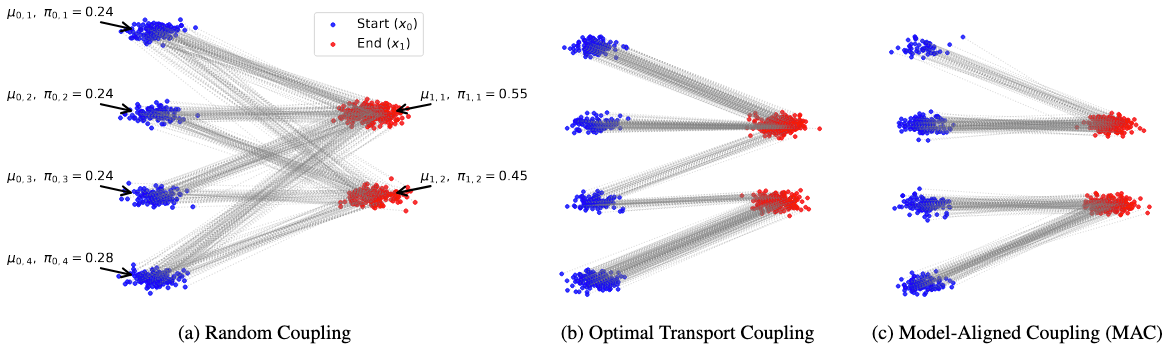
Beyond Optimal Transport: Model-Aligned Coupling for Flow Matching
Yexiong Lin, Yu Yao, Yang Zhou, Tongliang Liu CVPR, 2026 Findings [Project Page] [Paper] [Code] A coupling selection algorithm that better aligns with the learned model. |
|
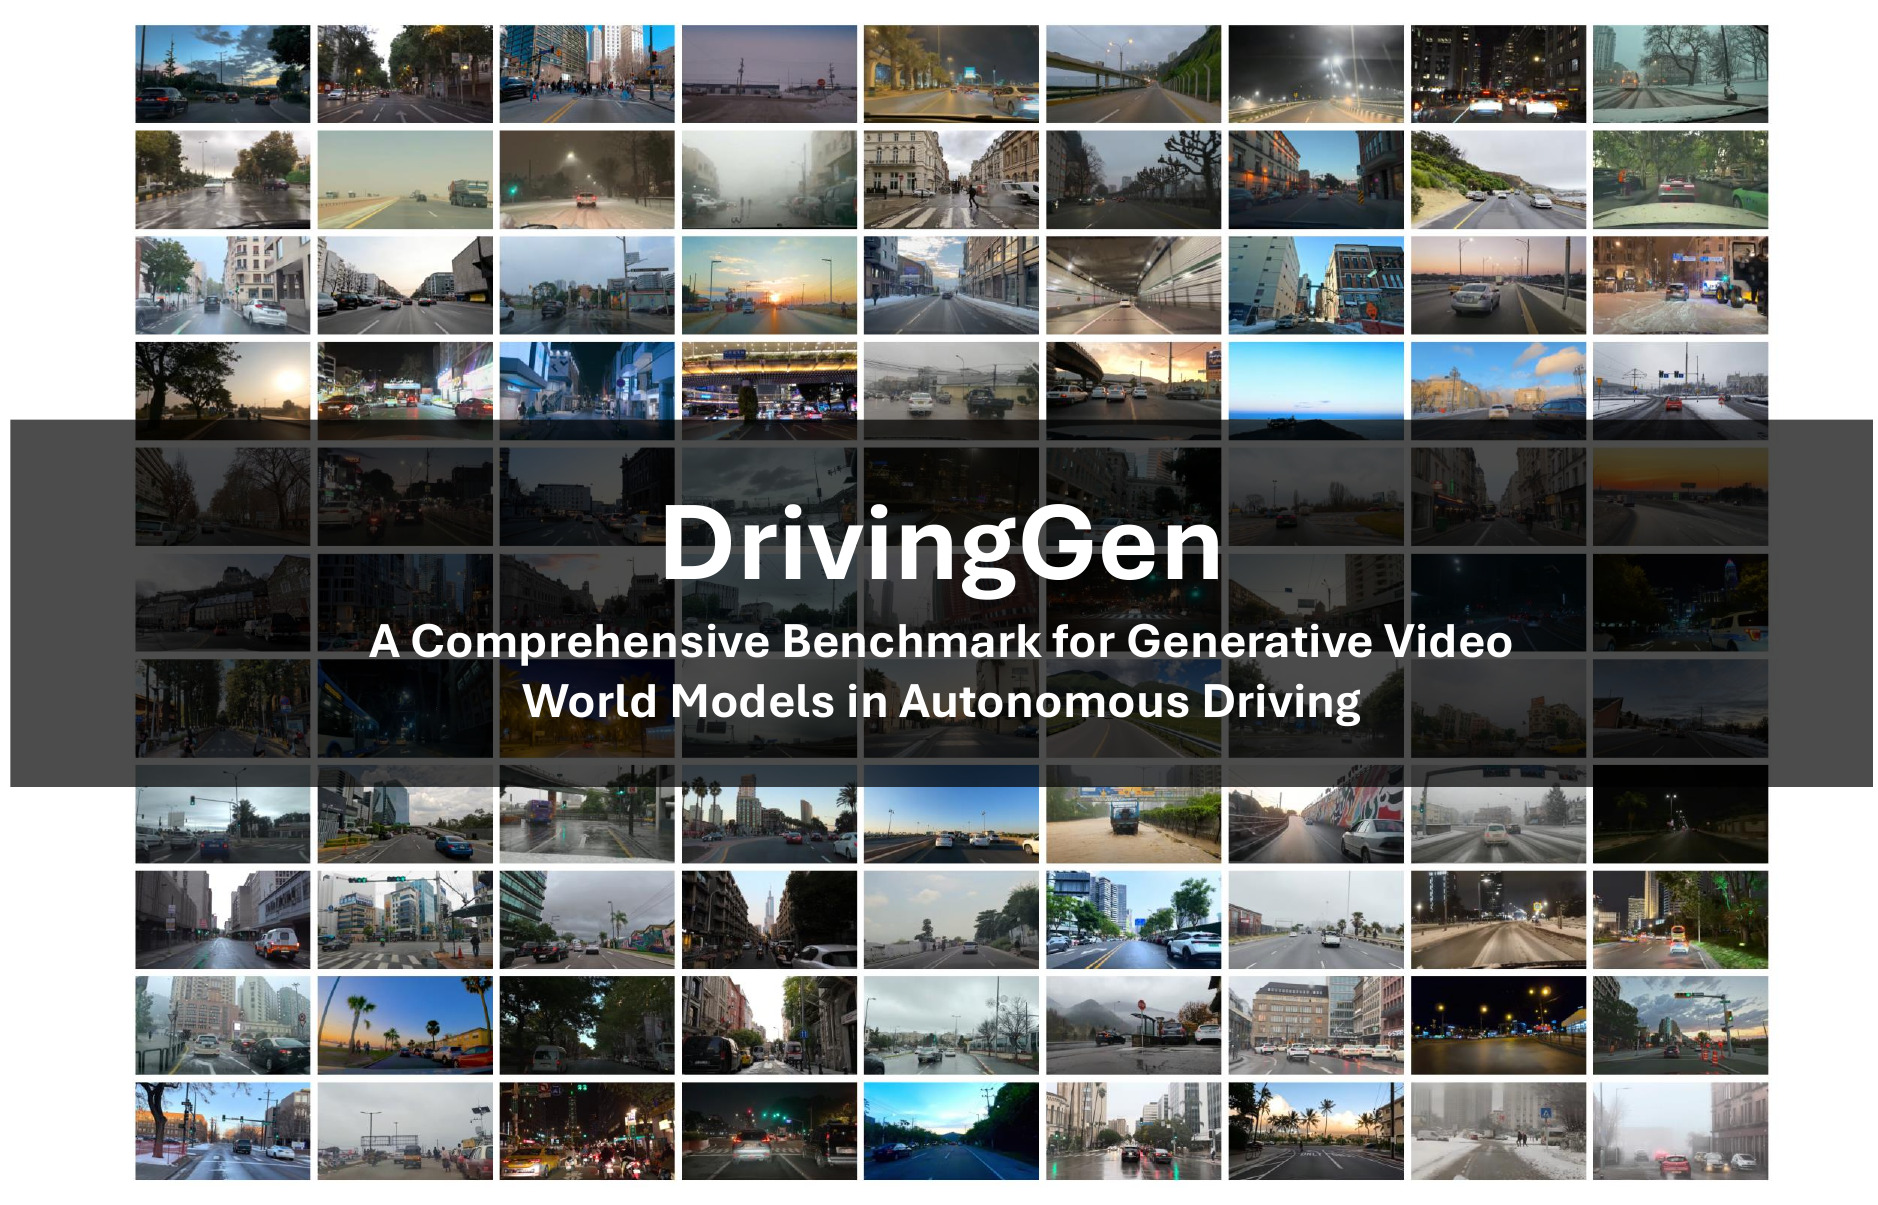
DrivingGen: A Comprehensive Benchmark for Generative Video World Models in Autonomous Driving
Yang Zhou*, Hao Shao*, Letian Wang, Zhuofan Zong, Hongsheng Li, Steven L. Waslander ICLR, 2026 [Project Page] [Paper] [Code] The first comprehensive benchmark for generative driving world models. |
|
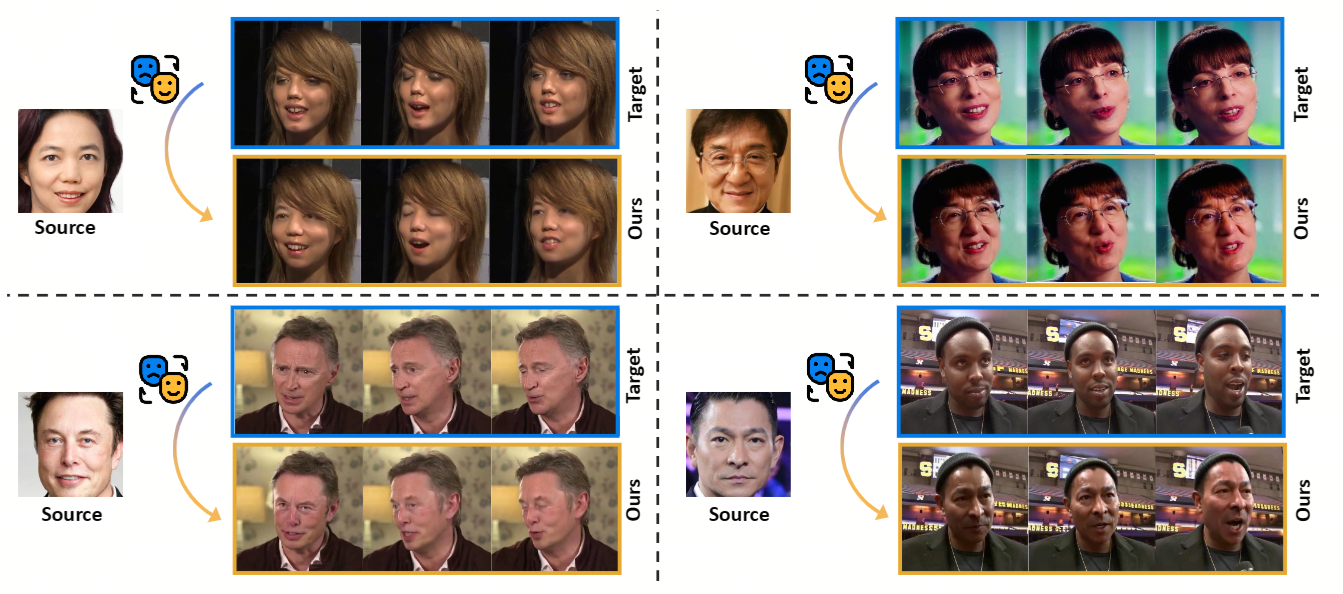
VividFace: A Diffusion-Based Hybrid Framework for High-Fidelity Video Face Swapping
Hao Shao, Shulun Wang, Yang Zhou, Guanglu Song, Dailan He, Shuo Qin, Zhuofan Zong, Bingqi Ma, Yu Liu, Hongsheng Li NeurIPS, 2025 [Project Page] [Paper] [Code] A diffusion-based framework for video face swapping with superior identity preservation and temporal consistency. |
|
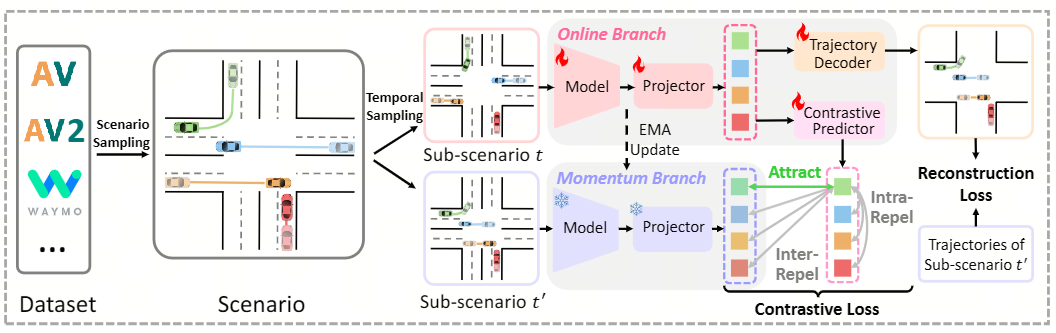
SmartPretrain: Model-Agnostic and Dataset-Agnostic Representation Learning for Motion Prediction
Yang Zhou*, Hao Shao*, Letian Wang*, Steven L. Waslander, Hongsheng Li, Yu Liu ICLR, 2025 [Paper] [Code] A general and scalable self-supervised pretraining framework for motion prediction, designed to be both model-agnostic and dataset-agnostic. |
|
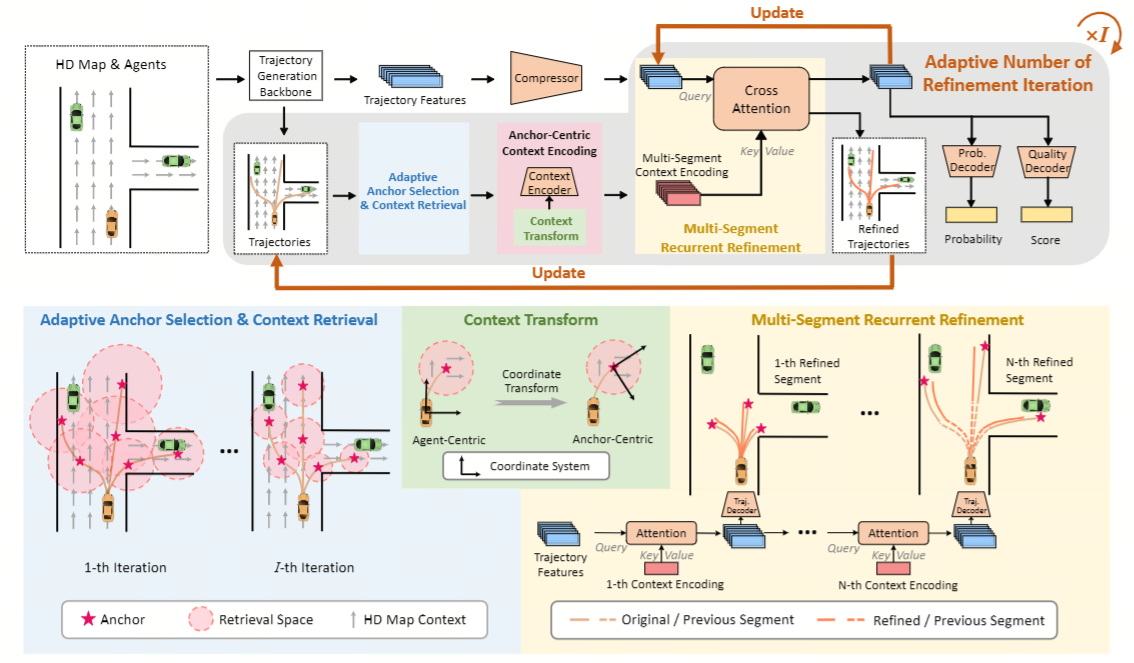
SmartRefine: A Scenario-Adaptive Refinement Framework for Efficient Motion Prediction
Yang Zhou*, Hao Shao*, Letian Wang, Steven L. Waslander, Hongsheng Li, Yu Liu CVPR, 2024 [Paper] [Code] A scenario-adaptive multi-round refinement strategy that boosts trajectory prediction with minimal extra compute. |
Service |
|
Conference Reviewer: ICLR 2027, 2026, 2025 ICRA 2027 CVPR 2026, 2025 ECCV 2026 NeurIPS 2026 |
|
Journal Reviewer: TVCG |
|
Template inspired by Jon Barron. |